Automating repetitive tasks is a common goal in business operations, promising greater efficiency and consistency. Yet, not all aspects of a process are suitable for automation—especially when it comes to handling exceptions or unpredictable scenarios. At E Tech Code, we have found value in automating the main flow of a process while deliberately managing exceptions through human oversight and internal controls. This approach allows for reliable automation without sacrificing quality or control in exceptional cases. In this article, we outline how to select a repetitive task for automation, define its inputs, review mechanisms, outputs, and boundaries, and maintain robust exception handling.
Selecting a Repetitive Task for Automation
The foundation of effective process automation is the careful selection of the task to be automated. The ideal candidate is a task that is repetitive, well-structured, and has clear, predictable outcomes. In our operations, tasks such as data validation and deduplication exemplify this profile. These activities are governed by explicit rules and can be executed consistently by automated systems.
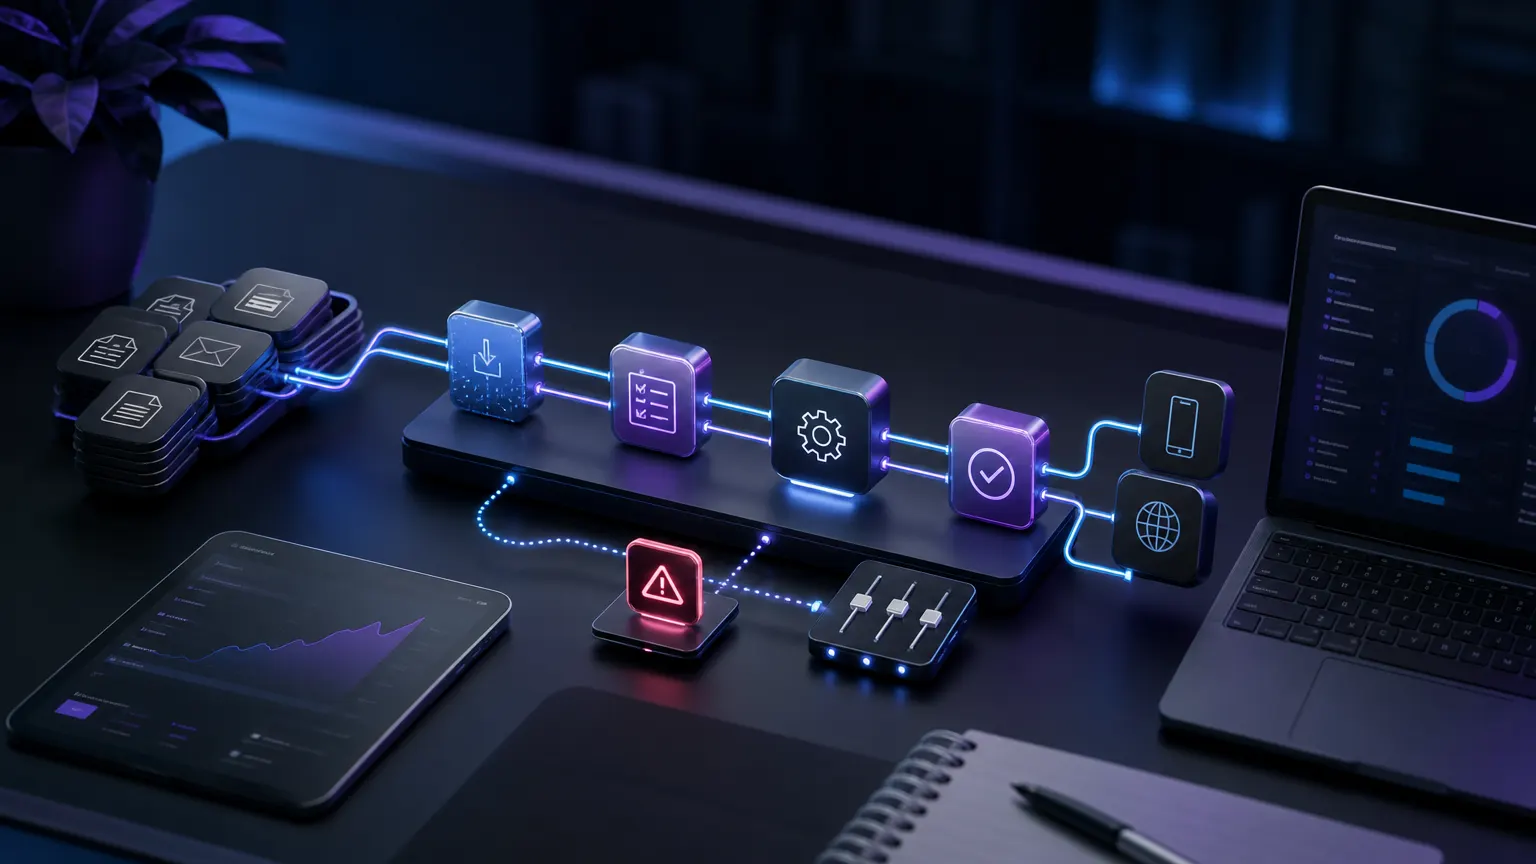
However, we intentionally exclude exceptions from the automation scope. This means that while the primary workflow is automated, any deviations or ambiguous situations are routed for human review. By doing so, we avoid the pitfalls of automating complex or context-dependent decisions that could introduce errors or unintended effects. This separation ensures that automation delivers efficiency where it is most effective, while exceptions receive the attention they require.
Defining Inputs with Clarity and Rigor
Once a task is selected, the next step is to define its inputs with precision. Inputs must be structured, validated, and consistent to ensure the automation operates as intended. At E Tech Code, we implement upfront validations to detect and address data issues early in the process. This includes verifying data formats, completeness, and logical consistency before the task enters the automated workflow.
By enforcing strict input controls, we minimize the risk of exceptions occurring later in the process. This proactive approach not only supports the reliability of the automation but also reduces the workload on human reviewers by preventing avoidable anomalies from progressing through the system.
Establishing Review Mechanisms for Exceptions
Since exceptions are not automated, it is essential to design clear review mechanisms. In our internal operations, when an outcome from a remote process is uncertain or falls outside expected parameters, the system triggers a human reconciliation step. This checkpoint ensures that any anomalies or inconsistencies are assessed and resolved by experienced personnel.
This division of labor—automation for the routine, human oversight for the exceptional—enables us to maintain high standards of reliability without overcomplicating the automated logic. It also ensures that human expertise is reserved for cases where judgment and context are critical, supporting both operational quality and trust in the process.
Defining Outputs and Their Internal Role
Outputs from the automated task must be clearly defined and reliable within the established boundaries. For example, after automated validation and deduplication, the output is a refined dataset that is ready for subsequent processing or storage. It is important to recognize that these outputs represent internal system states and controls, not guarantees of external business outcomes.
This distinction is crucial: automation is a tool for improving internal processes, not a promise of specific results for clients or external stakeholders. By framing outputs as internal controls, we set appropriate expectations and clarify the role of automation within the organization.
Setting Boundaries to Contain Automation Risks
A key aspect of this approach is the explicit definition of boundaries for automation. We limit automation to the main process flow, deliberately excluding exception handling from automated routines. This boundary-setting is a risk management strategy, preventing the escalation of errors and maintaining operational stability.
Alternative approaches, such as attempting to automate all exceptions, were considered but ultimately set aside. The complexity and unpredictability of certain scenarios made full automation impractical and potentially risky. By drawing clear boundaries, we ensure that automation remains manageable and that exceptions are addressed with the necessary care.
Practical Steps and Lessons Learned
For organizations considering a similar strategy, several practical steps can guide implementation:
- Map the process thoroughly to identify repetitive tasks with stable, well-defined inputs and outputs.
- Apply rigorous input validations to catch errors early and reduce the frequency of exceptions.
- Design the workflow to include explicit human review points for handling anomalies or uncertain outcomes.
- Clearly define outputs as internal controls, not external guarantees, to manage expectations appropriately.
- Set and communicate boundaries that separate automated flows from exception handling, supporting effective risk management.
- Periodically review data quality, the frequency of exceptions, and the complexity of decision points to refine the scope of automation and oversight.
In summary, automating a process without automating its exceptions is a pragmatic and balanced approach. By focusing automation on well-defined, repetitive tasks and reserving human oversight for exceptions, organizations can achieve efficiency while maintaining control and quality. This method, supported by internal controls such as validations, deduplication, durable reservations, and human reconciliation, provides a robust framework for reliable business operations.
Explore our website, process automation and app improvement offers. Scope is agreed after reviewing your needs.